
For Muawia Tech readers, generative AI data leakage controls matters because it links everyday technology decisions to security, resilience, governance, and operational control. This is more than a headline. It is a practical planning concern for security leaders, IT teams, cloud administrators, and business owners.
A practical approach starts by looking past the hype and asking operational questions. What problem does it solve? Which users will it affect? What data or permissions does it involve? Which processes need to change? What evidence shows that the new approach is safer, faster, or more reliable than the current one?
Why Generative AI Data Leakage Controls matters now
Organizations face growing pressure to adopt new technology without exposing themselves to unmanaged risk. In practice, evaluating generative AI data leakage controls means considering its business impact, how people will use it, the data it may expose, and whether it can be maintained over time. Even a topic that seems straightforward can affect procurement, training, compliance, customer trust, and daily operations.
Assign one person to own generative AI data leakage controls and give them the authority to pause the rollout when the evidence is weak or the controls fail.
Main risks and opportunities
The benefits are clear: faster work, better decisions, stronger controls, and less time wasted on manual tasks. The risks are just as clear. Teams may adopt a tool or process before they fully understand its limits. Common problems include weak ownership, missing logs, vague approval rules, poor documentation, and too much confidence in automation. A practical plan should weigh the benefits against realistic ways the system could fail.
Document the assumptions behind the pilot. If the results do not match expectations, the team can adjust the design rather than defend an outdated plan.
How teams should evaluate it
Begin by mapping the workflow. Identify who uses it, what information enters the process, where decisions happen, and which systems it touches. Next, review identity controls, endpoint visibility, backup readiness, patching practices, SaaS permissions, cloud logging, and responsibility for incident response. Even a simple map can show whether the issue lies mainly in training, tools, governance, or the underlying architecture.
Choose a small test group that reflects real working conditions. A pilot that excludes difficult users, sensitive data, or peak workloads will produce misleading evidence.
A practical implementation framework
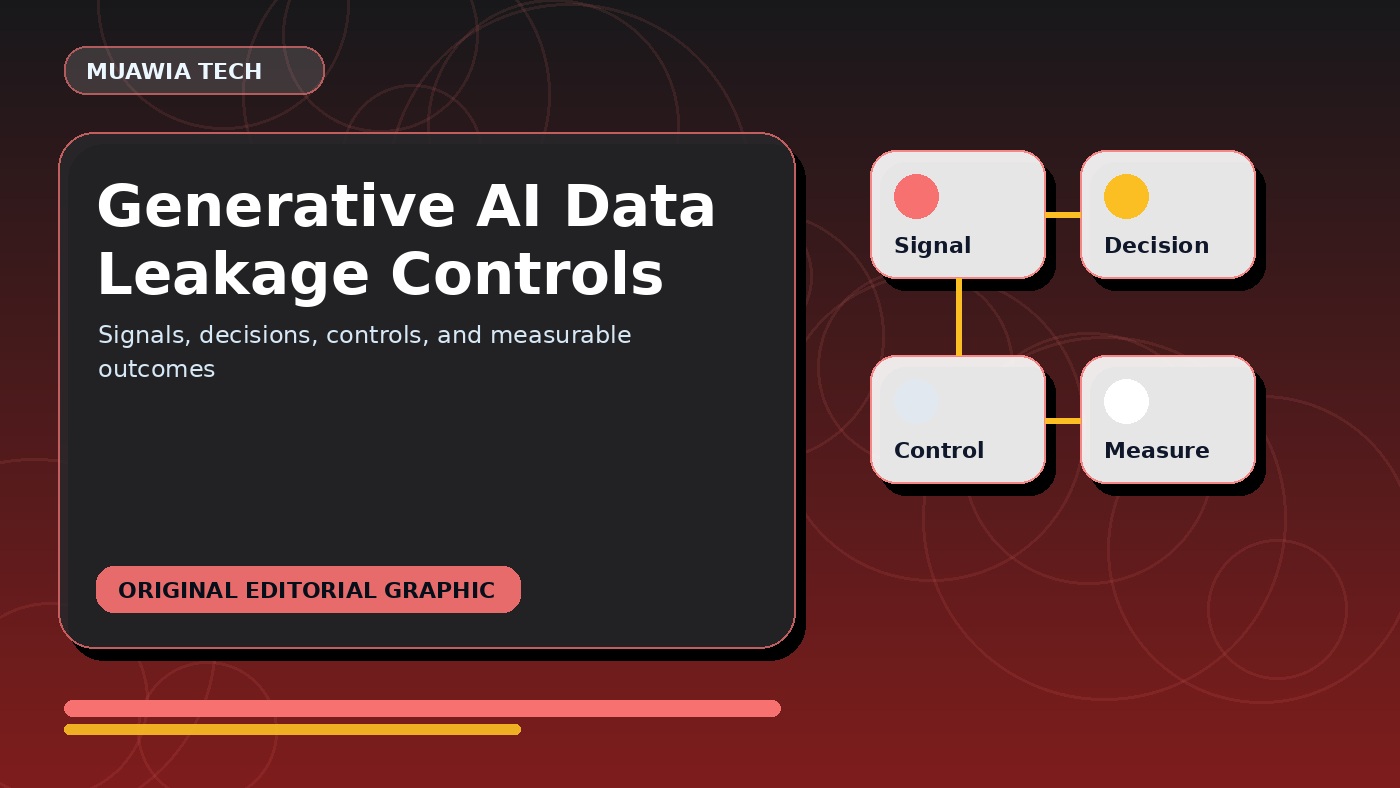
A safe implementation can follow this sequence: inventory assets, assign owners, score risks, review policies, run a pilot, monitor performance, document the process, and make quarterly improvements. This keeps the project grounded in evidence. Rather than introducing a broad change all at once, teams can test the approach with a small group, measure the results, address weak points, and then expand with confidence.
Document the exception process before launch. Staff need to know who can approve unusual cases, where to log incidents, and when to involve the security or legal teams.
What good governance looks like
Good governance is not a lengthy document that no one reads. It is a clear set of rules built around how people work. These rules should cover acceptable use, approval requirements, data boundaries, escalation paths, monitoring expectations, and review cycles. Users are more likely to follow governance when it is practical and easy to find.
Review metrics in context instead of assuming every increase signals progress. Faster completion helps only if quality, access control, and recovery remain acceptable.
Metrics to track
Teams should track adoption, time saved, error reduction, avoided incidents, support tickets, user satisfaction, and policy exceptions. Each metric should inform a decision. If a feature saves time but causes more review failures, adjust the process. If a control reduces risk but prevents legitimate work, the rollout may need clearer training or more precise rules.
Test the recovery path with the same care as the normal workflow. Teams need to know how to revoke access, restore data, investigate logs, and return to a known safe process.
Common mistakes to avoid
A common mistake is treating a trend as a complete solution. Another is overlooking the users who must apply it under pressure. Teams may also fail to document recovery paths for when something goes wrong. Finally, measuring activity alone, such as the number of users or prompts, says little about outcomes such as quality, safety, or business value.
End the pilot with a written decision to expand, revise, or stop it. Recording the decision prevents the experiment from becoming permanent simply because no one reviewed it.
Internal links and further reading
For more on risk management, AI adoption, cloud operations, and productivity workflows, read the related guides in Security and Cloud.
FAQ
Is Generative AI Data Leakage Controls intended only for large organizations?
No. Smaller teams often need simple, repeatable processes just as much as large enterprises, if not more. Start with one high-value workflow and keep the rollout manageable.
What is the safest first step?
Begin with an inventory and a pilot. Select one workflow, set clear success criteria, identify the risks, and test it with a small group before expanding.
How often should you review the process?
Review the process after the initial pilot, again after the first month of wider use, and then every quarter. Regular checks are necessary because the technology, its risks, and user habits can change quickly.
What should leaders ask before approving adoption?
Ask which problem the workflow solves, what data it uses, who owns the process, how the team will check the results, and what happens if the tool or workflow fails.
Conclusion
generative AI data leakage controls should be approached as a practical operating decision. Teams are more likely to get value when they define the use case, manage the risks, train users, measure outcomes, and keep improving the workflow. This turns a current topic into a capability that lasts.
Step-by-step rollout plan
Start by documenting the current process and its pain point. Then define the desired result in measurable terms. List every system, user, data source, and permission affected by the change. Set up a pilot group with clear start and end dates, and collect examples of both successful and failed outputs. Update the guidance based on what you learn before expanding the rollout. Following this sequence helps teams avoid scaling confusion.
Security and privacy review
Every modern technology workflow needs a privacy review. Teams must understand whether sensitive data is entered, stored, exported, or shared with third parties. Only people who need access should have it, and logs should be kept long enough to investigate problems. Workflows involving customers, finance, health, legal matters, or internal strategy require stricter approval rules.
Train users without slowing them down
Training works best when it is brief, specific, and tied to the user’s work. Provide examples they can copy, screenshots showing the correct steps, and a simple checklist for risky situations. Skip abstract policy language. Users should know exactly what to do when they encounter an unexpected result, receive a suspicious request, or face a task that needs human review.
How to keep improving
Once the system is live, gather feedback from users and reviewers. Watch for recurring errors, unclear prompts, unnecessary approvals, and missing integrations. Make improvement a scheduled process rather than leaving it to chance. A monthly review gives you time to remove friction, update templates, retire ineffective steps, and make successful experiments part of your standard operating procedures.
Decision checklist for managers
Managers should confirm the owner, scope, user group, data boundary, approval path, and success metric. They should also identify which tasks will stop or become simpler after the team adopts the new workflow. Without this discipline, teams risk adding more tools while keeping the old manual work in place. That weakens the business case and causes confusion.
Operational playbook
A practical playbook should cover normal use, exception handling, review responsibilities, and rollback steps. It should identify the person or team responsible for updates and provide examples of acceptable and unacceptable use. This helps teams audit the workflow, train users, and make improvements when new risks or opportunities arise.
Evidence register
Keep a clear record of the evidence behind each rollout decision. Note the test performed, who reviewed it, the expected result, the actual outcome, and any limitations that could affect the conclusion. This gives future reviewers the context they need to understand why the team expanded, changed, or stopped the workflow. It also ensures that a confident summary does not replace the details required for security, quality, or operational review.
Stakeholder review
Include the people who run the process in the review before a wider launch. Technical owners can explain the system’s limits, while daily users can spot steps that seem practical on paper but break down under time pressure. Bring in security, privacy, legal, or customer service reviewers when the workflow affects their areas. Document unresolved concerns, then assign each one an owner and a deadline. Attendance alone should not count as approval.
Cost and value check
Compare the workflow’s full operating cost with the results it produces. Account for setup, licenses, training, review time, maintenance, support, and the work needed when outputs fail. Weigh those costs against measurable changes in completion time, quality, risk, or service capacity. This helps teams separate a genuinely useful capability from a tool that looks impressive in demonstrations but creates more work in production.
Communicating the change
Tell affected users what will change, what will remain the same, and where to get help. Explain the practical reasons for the new workflow instead of using vague slogans about transformation. Give people a clear date, brief instructions, and a way to report problems. Review early feedback promptly so that avoidable friction does not become a permanent part of the process.
Post-launch review
Schedule a formal review once the workflow has processed enough real work to reveal what works and where problems arise. Compare the results with the original baseline, examine exceptions and support requests, and confirm whether users follow the documented process. Then decide which controls or templates need updating and whether the expected value supports continued operation. Publish the decision internally to give the next review a clear starting record.